Multi-agent Markov Decision Processes · Inverse Reinforcement Learning · Moving Target Defense
Deceptive Sequential Decision-Making via Regularized Policy Optimization
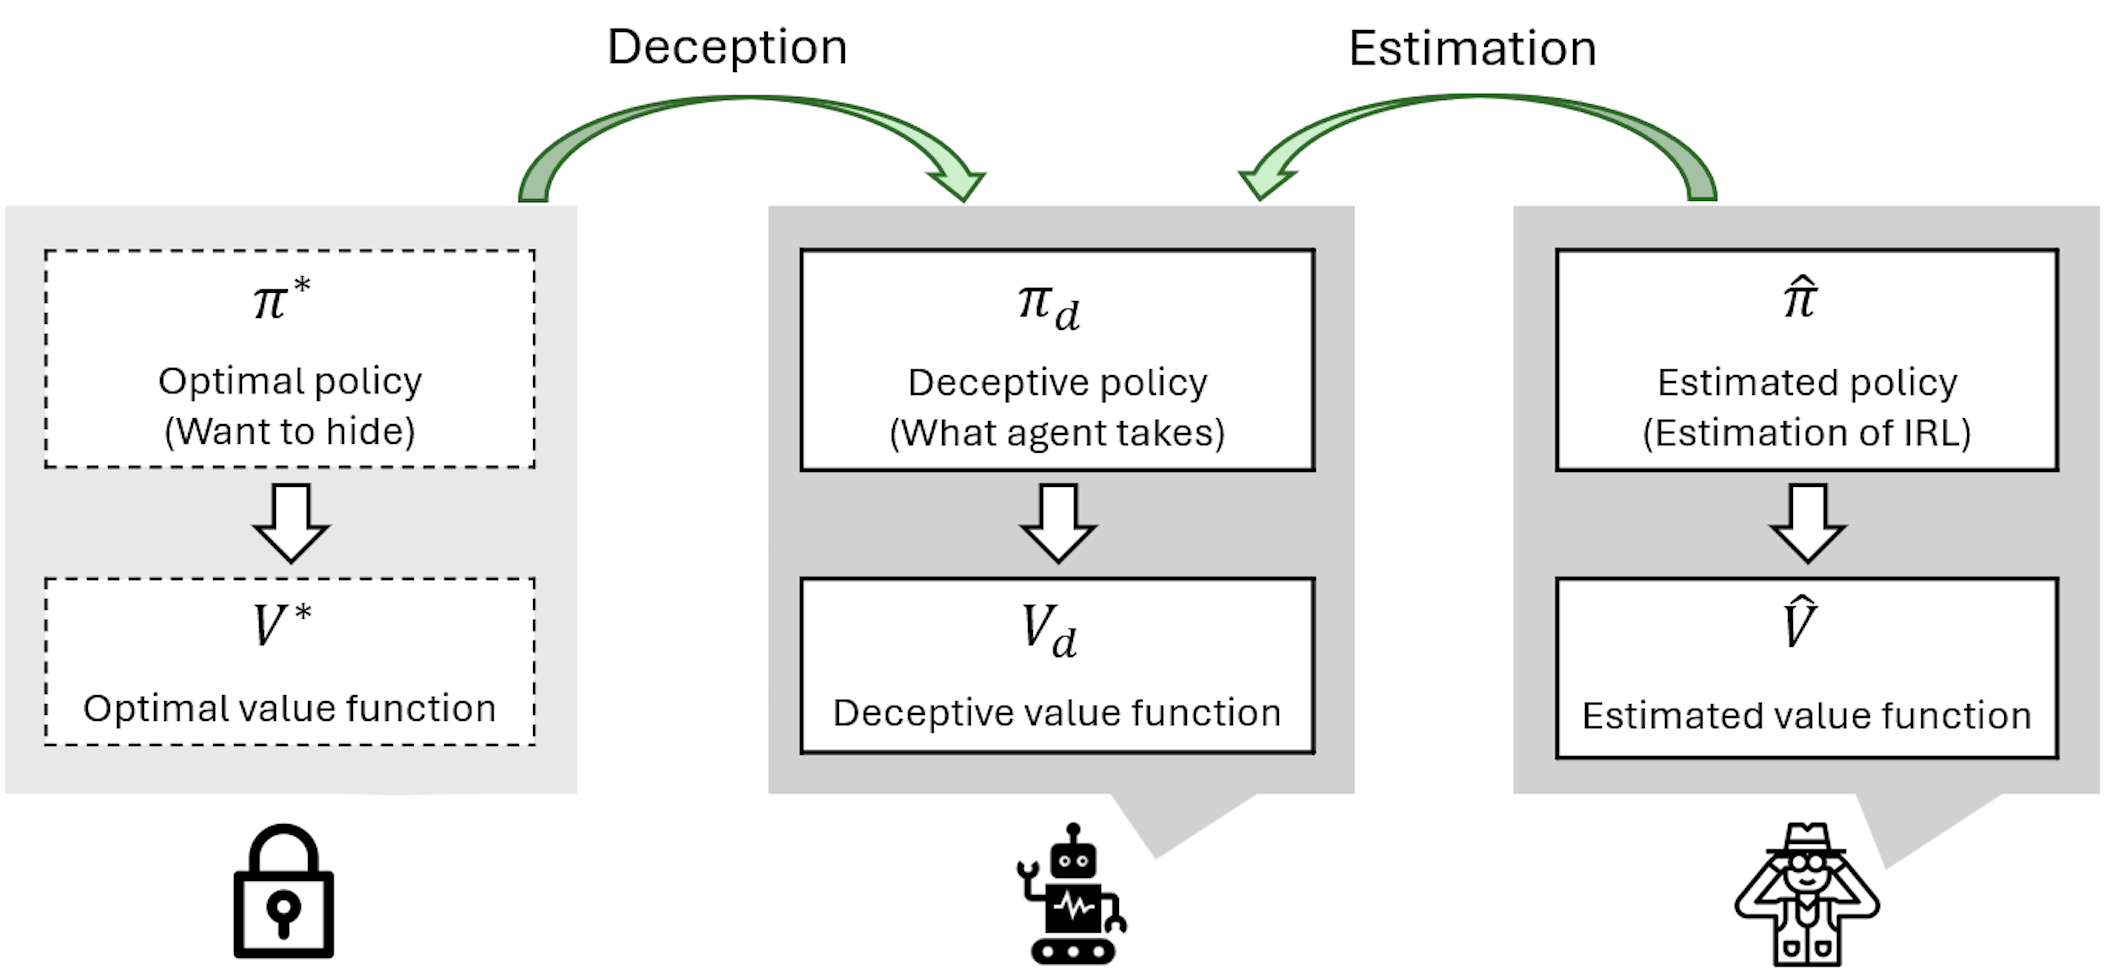
In Markov Decision Processes, an observer can infer an agent’s underlying objectives from its behavior using inverse reinforcement learning (IRL). We design policy regularizers that steer these inferences toward false rewards while preserving task performance.
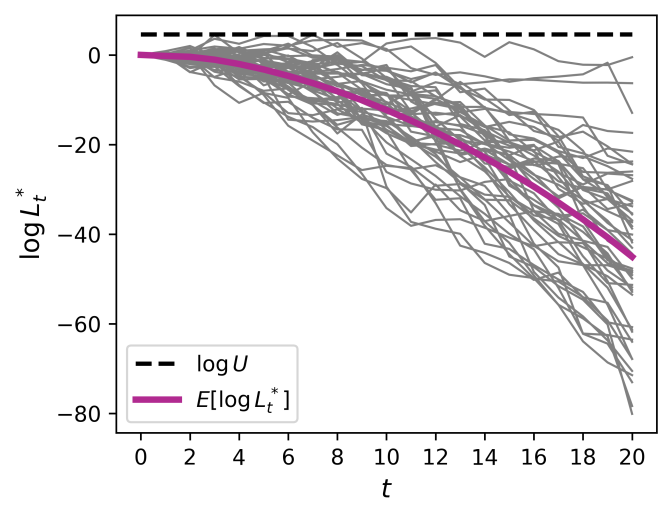
Key result. We derive bounds on accumulated reward loss as a function of regularization strength. In the paper’s network-defense simulations, the three deception strategies induced false beliefs in three different IRL algorithms, while retaining at least 98% of optimal non-deceptive reward.
Read conference paper ↗Read journal extension (preprint) ↗Explore code ↗View slides ↗